Microservices: When They Make Sense (and When They Don't)
What microservices actually are per Lewis and Fowler, prerequisites, distributed system overhead, and lessons from Segment, Prime Video, and Shopify.

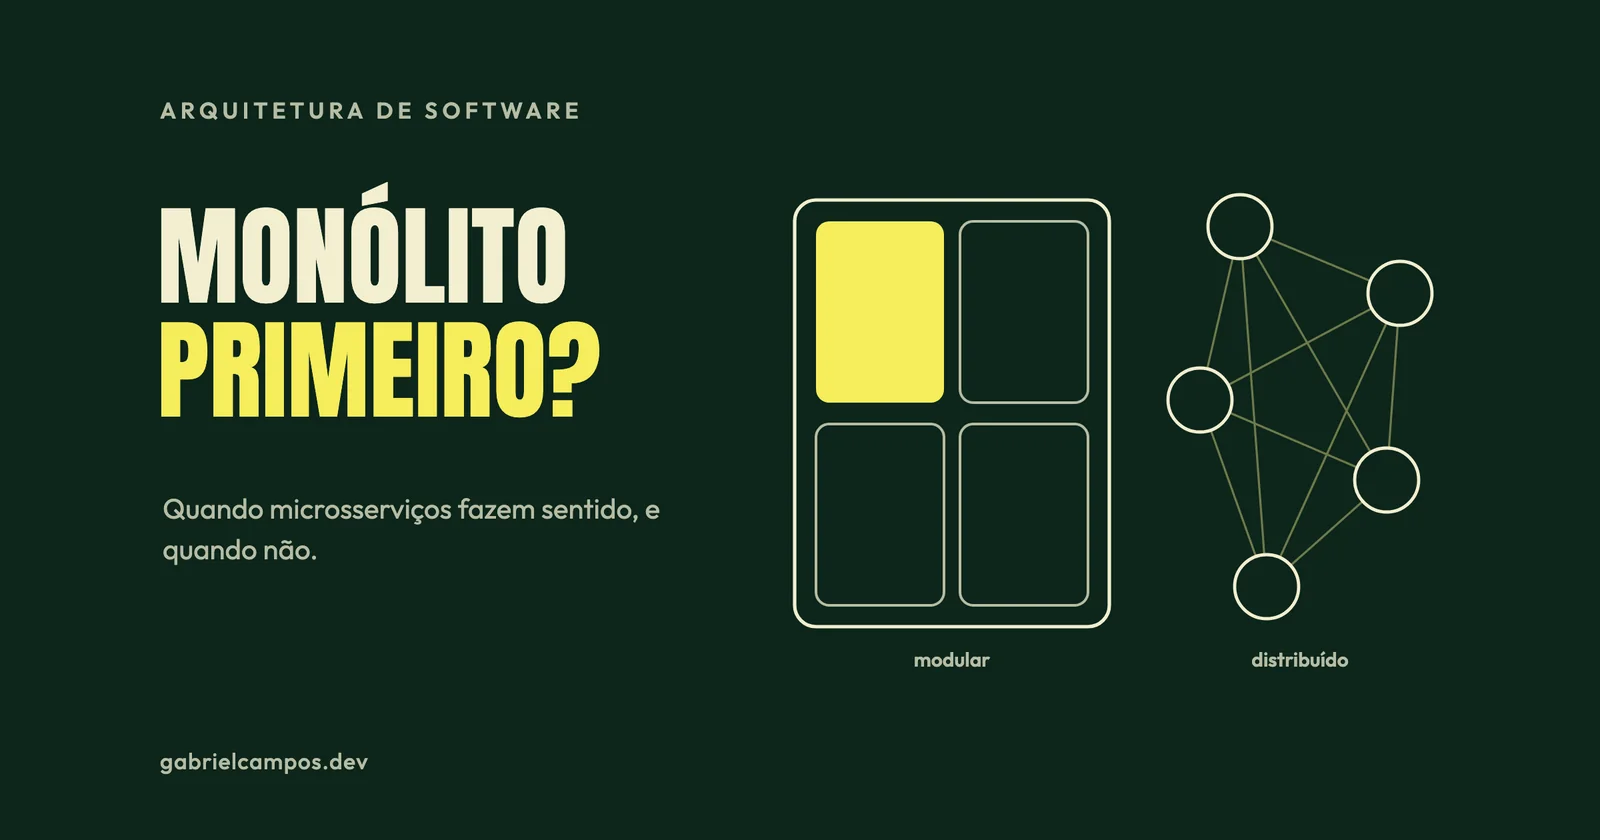
Few architectural decisions are adopted with as much dogmatic conviction and as little empirical evidence as “let’s build it as microservices.” The architecture genuinely solves serious engineering bottlenecks at scale, but it extracts an immense operational price—a price routinely paid by engineering teams that do not yet suffer from the problems microservices were designed to solve.
In this article, I revisit the foundational definition, the operational prerequisites articulated by early advocates, and three well-documented public case studies that calibrate this decision: Segment, Prime Video, and Shopify.
What microservices actually are
The seminal definition is the article Microservices, published by James Lewis and Martin Fowler in March 2014. They describe the architectural style as an approach to developing an application as a suite of independently deployable services, explicitly acknowledging that no single rigid definition exists. Instead, they identify recurring common characteristics:
- Componentization via services;
- Organization structured around business capabilities;
- Products rather than project handoffs;
- Smart endpoints and dumb pipes;
- Decentralized governance;
- Decentralized data management (each service private to its data);
- Infrastructure automation;
- Design for failure;
- Evolutionary design.
The core prerequisite is independent deployment. If releasing a routine feature requires orchestrating the coordinated deployment of five separate services simultaneously, you do not have microservices: you have a distributed monolith, bearing all the operational latency and failure modes of distributed systems without their primary organizational benefit.
What you gain
- Independent deployment: individual product teams ship releases at their own velocity.
- Team autonomy: clear codebase boundaries aligned with organizational accountability.
- Targeted scaling: CPU- or memory-intensive services scale horizontally without resizing the entire application footprint.
- Fault isolation, when architected properly: an outage in a recommendation service does not bring down checkout.
- Polyglot flexibility: teams can select specialized runtimes or databases suited to specific domain problems.
What it costs
Every architectural benefit above arrives tightly coupled with the realities of distributed computing:
- The network is fallible. Inter-service RPCs introduce network latency, connection timeouts, and partial failure modes that never existed within in-process function invocations.
- Data consistency becomes an architectural burden. Without a shared database, cross-domain operations cannot execute within a single ACID transaction. Patterns like the Saga pattern resolve this, but introduce significant stateful complexity.
- Observability is mandatory. Without centralized structured logging, Prometheus-style metrics, and distributed tracing, debugging an error spanning six microservices becomes digital archaeology.
- Operational overhead. More CI/CD pipelines, more Git repositories, complex configuration drifts, and more base container dependencies to patch.
In 2014, Fowler outlined three operational prerequisites that an engineering organization must satisfy before adopting microservices: rapid infrastructure provisioning, basic monitoring and alerting, and rapid application deployment. If a team struggles to maintain these for a single application artifact, multiplying the service count merely multiplies the operational dysfunction.
Monolith First
In June 2015, Fowler published Monolith First, capturing an observation shared by seasoned architects: almost all successful microservice architectures originated from a monolith that grew too large and was subsequently decomposed. Conversely, virtually every system engineered as microservices from day one ran into severe structural trouble.
The reason is pragmatic: in the early stages of a product, nobody understands where the true domain boundaries lie. Drawing the wrong boundary inside a monolith requires an internal code refactoring. Drawing the wrong boundary across distributed microservices requires complex data migrations, breaking API contract negotiations, and multi-team coordination.
Three public case studies
Segment: from over 140 microservices back to one
In July 2018, Alexandra Noonan published Goodbye Microservices on the Segment engineering blog. The company had originally architected one dedicated microservice (and message queue) per integration destination, eventually scaling to more than 140 separate services. Documented operational pain points:
- Operational maintenance overhead scaled linearly with every new destination added;
- Three full-time engineers spent the majority of their working hours merely keeping the distributed worker fleet operational;
- Shared libraries suffered version drift across repositories;
- Automated test suites depended on live HTTP network stubs and failed intermittently.
The solution was consolidating all destinations into a single unified service within a monorepo, pinning shared dependencies to a single version. The post concluded that moving to a monolith eliminated ongoing operational overhead and dramatically increased developer productivity. The author was equally transparent regarding the trade-off: fault isolation within the process became more challenging.
Prime Video: a targeted optimization, not a universal dogma
In 2023, the Video Quality Analysis team at Prime Video documented migrating an automated stream monitoring tool from a distributed serverless architecture (AWS Step Functions orchestrating AWS Lambda functions, buffering intermediate video frames in Amazon S3) into a consolidated service running on Amazon ECS. Per InfoQ coverage, the serverless architecture hit hard cost and throughput bottlenecks at roughly 5% of target load, primarily driven by Step Functions state transition charges and high-frequency S3 read/write IOPS. Consolidating the pipeline into a single process handling video frames in local memory reduced operational infrastructure costs by 90%.
While social media simplified the story into “Amazon abandons microservices,” the engineering authors were explicit: the distributed serverless architecture was simply the wrong architectural fit for that specific high-throughput, compute-dense data pipeline. The architectural lesson: design must follow data flow characteristics and load profiles, not industry fashion.
Shopify: the modular monolith
In February 2019, Kirsten Westeinde published Deconstructing the Monolith on the Shopify engineering blog. Rather than decomposing their monolithic Ruby on Rails core into dozens of independent network services, Shopify preserved a single deployable codebase while strictly enforcing boundaries between internal components. This pattern is the modular monolith: a single deployable artifact containing deeply encapsulated modules with explicit public interfaces.
Architectural boundaries follow human organizations
Lewis and Fowler explicitly cite Conway’s Law (1968): organizations that design systems are constrained to produce designs which are copies of the communication structures of these organizations. In practice, service decomposition works best when it reflects distinct product teams possessing autonomous business domains. A small engineering team of six people maintaining fifteen microservices rarely reaps autonomy: they have merely created an unmanageable operations burden for themselves.
The recommended pragmatic baseline
My view: for the vast majority of growing software products, the most dependable, productive starting architecture is a modular monolith with explicit domain boundaries, where each module owns its private database tables and cross-module communication is restricted to public interface contracts. When a specific module genuinely requires independent autoscaling or separate release cadences, it is already structurally decoupled and ready to be extracted.
src/
  modules/
    orders/
      index.ts          ← sole public entry point of the module
      application/
      domain/
      infra/
    payments/
      index.ts
      ...
    inventory/
      index.ts
      ...
This structural rule is simple to understand and enforce via linters and code reviews: an external module may only import from another module’s index.ts, never its internal implementation files. I expand on this separation of concerns in the article on efficient web system architecture. If you are currently modernizing a sprawling legacy application, see the guide on legacy system modernization for incremental extraction patterns.
Decision checklist
Microservices typically make architectural sense when the majority of the following criteria evaluate to “yes”:
- Do you have multiple independent engineering teams that need to deploy features without cross-team deployment locks?
- Are domain boundaries stable, well-understood, and proven over time?
- Do distinct subdomains exhibit radically divergent scalability or hardware resource requirements?
- Does the team already possess fully automated CI/CD pipelines, rapid provisioning, and health monitoring?
- Does the organization have the operational tooling and expertise to manage distributed tracing, metrics, and structured logs?
- Can the business domain operate safely under eventual data consistency across boundaries?
If the honest answer to most of these questions is “no,” the architectural problem is almost certainly solved by disciplined internal modularity rather than proliferating network boundaries.
References
This article is a study based on the sources below. Passages marked as opinion reflect my own reading.
- James Lewis and Martin Fowler. Microservices (March 2014).
- Martin Fowler. Microservice Prerequisites (2014).
- Martin Fowler. Monolith First (June 2015).
- Alexandra Noonan, Segment. Goodbye Microservices: From 100s of problem children to 1 superstar (July 2018).
- Rafał Gancarz, InfoQ. Prime Video Switched from Serverless to EC2 and ECS to Save Costs (May 2023).
- Kirsten Westeinde, Shopify Engineering. Deconstructing the Monolith: Designing Software that Maximizes Developer Productivity (February 2019).
Need technical support for your software architecture or systems?
I build resilient custom web systems, high-throughput API integrations, and performance diagnostics. Direct collaboration with the engineer, zero intermediaries.
Related Articles
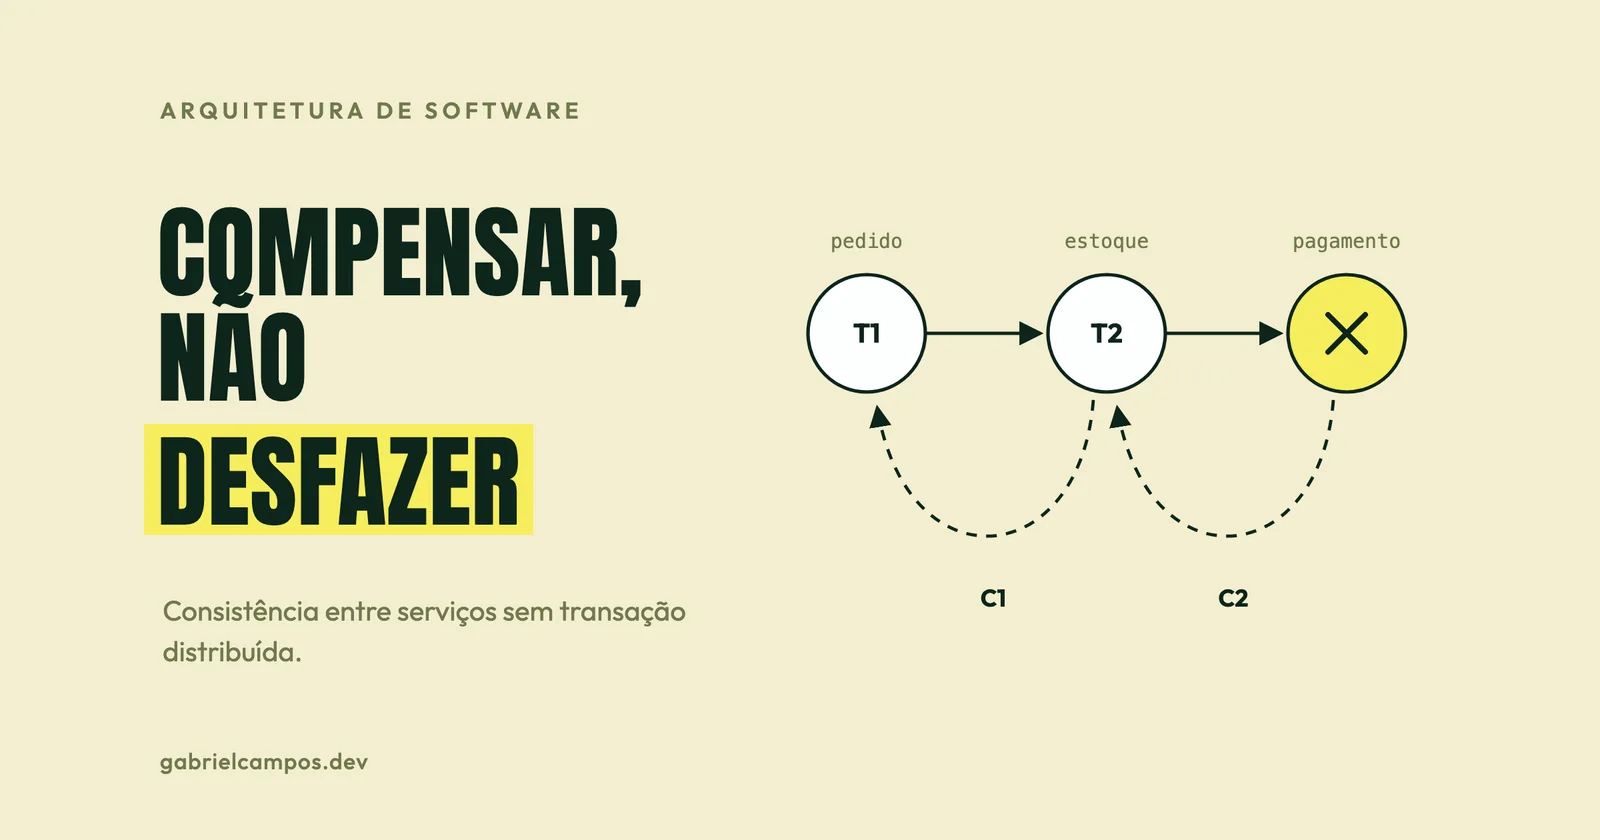
Saga Pattern: Distributed Transactions Without 2PC
How the Saga pattern preserves consistency across microservices: choreography vs. orchestration, compensating transactions, pivot steps, and transactional outbox.
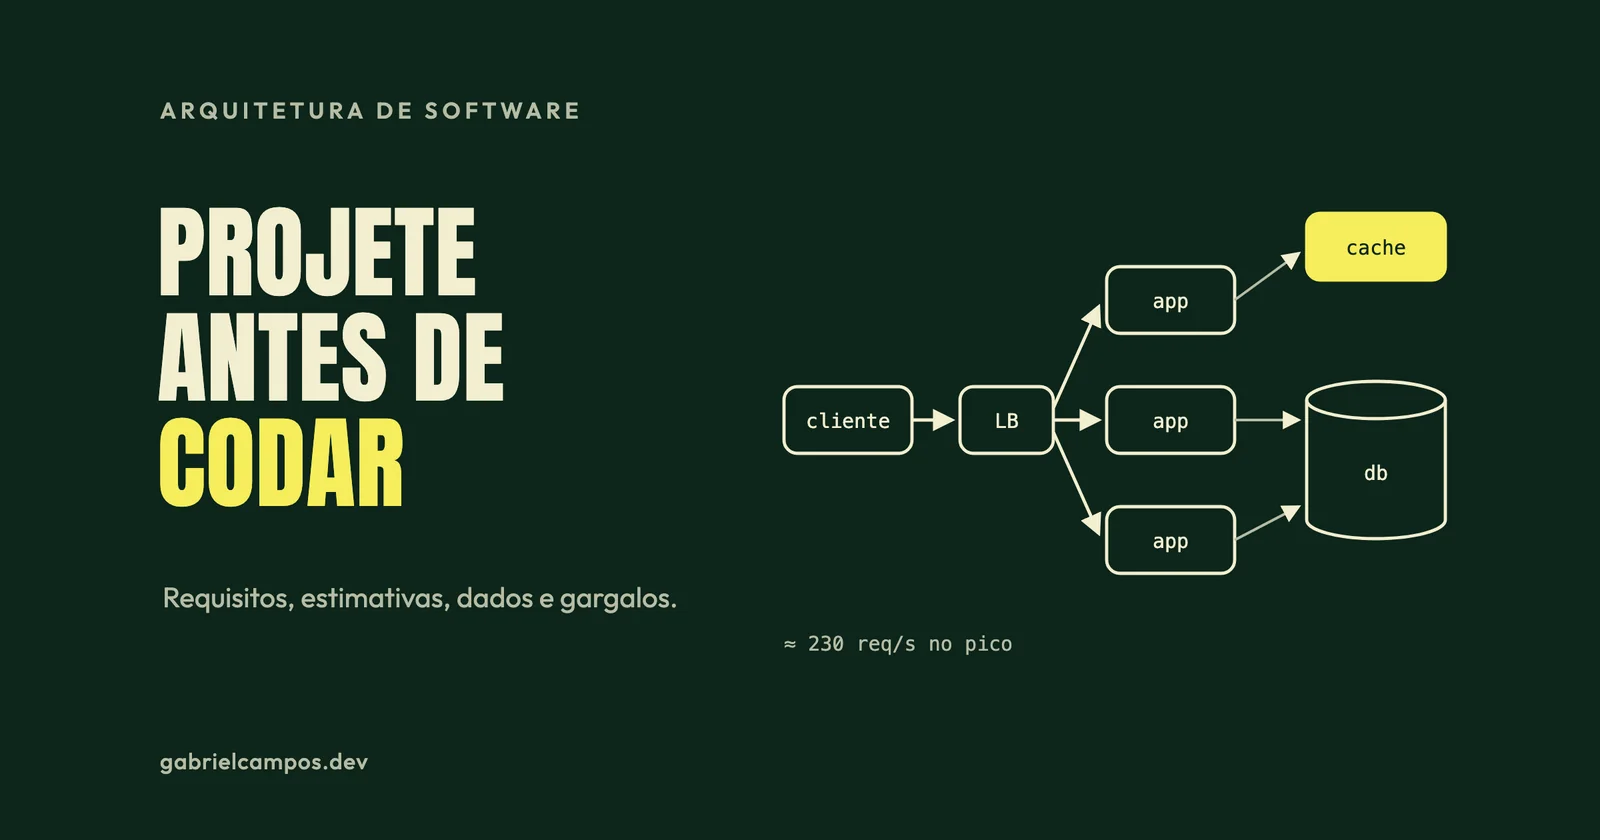
Practical System Design: A Roadmap Before Writing Code
A pragmatic system design roadmap for production software: requirements, back-of-the-envelope math, architecture, data modeling, bottlenecks, and trade-offs.